Bester Lokaler LLM-Chatserver
Ein Heimserver für privaten LLM-Chat (Ollama + Open WebUI), lokale Code-Vervollständigung und LoRA-Finetuning — viel VRAM, viel RAM.
- Lokale KI-Inferenz
- Code-Assistent (lokales LLM)
- Modelltraining / Fine-Tuning
Anforderungen vs. dieser Build
Bedarf · genutzt| CPU-Kerne | 18 / 20 | 90% | Knapp |
|---|---|---|---|
| RAM | 96 / 128 GB | 75% | OK |
| Speicher | 4 / 4 TB | 100% | Voll |
| GPU | KI-fähig |
Verbrauch
- Nutzung
- 24/7
- Leerlauf
- 115 W
- Typisch
- 143 W
- Spitze
- 698 W
- Energie / Jahr
- ≈ €314
- Über 3 Jahre
- ≈ €942
Score
Warum diese Variante
Balances your priorities with a 8430€ price tag and a 115W idle draw.
- Not specialized: it does not push any single dimension (value, silence, expansion) to the extreme.
- Intel Core i7 14700: 20 cores / 28 threads covers the 18 cores needed with headroom.
- Motherboard Intel B760 (LGA 1700): matches the CPU socket and case size.
- RAM: 128GB DDR5,DDR4 — meets the 96GB the workload requires.
- All variants are close; the winner matches your priorities best.
Vor dem Kauf
Vor dem Kauf ist nichts Kritisches zu beheben.
 €344Preise werden gesucht…
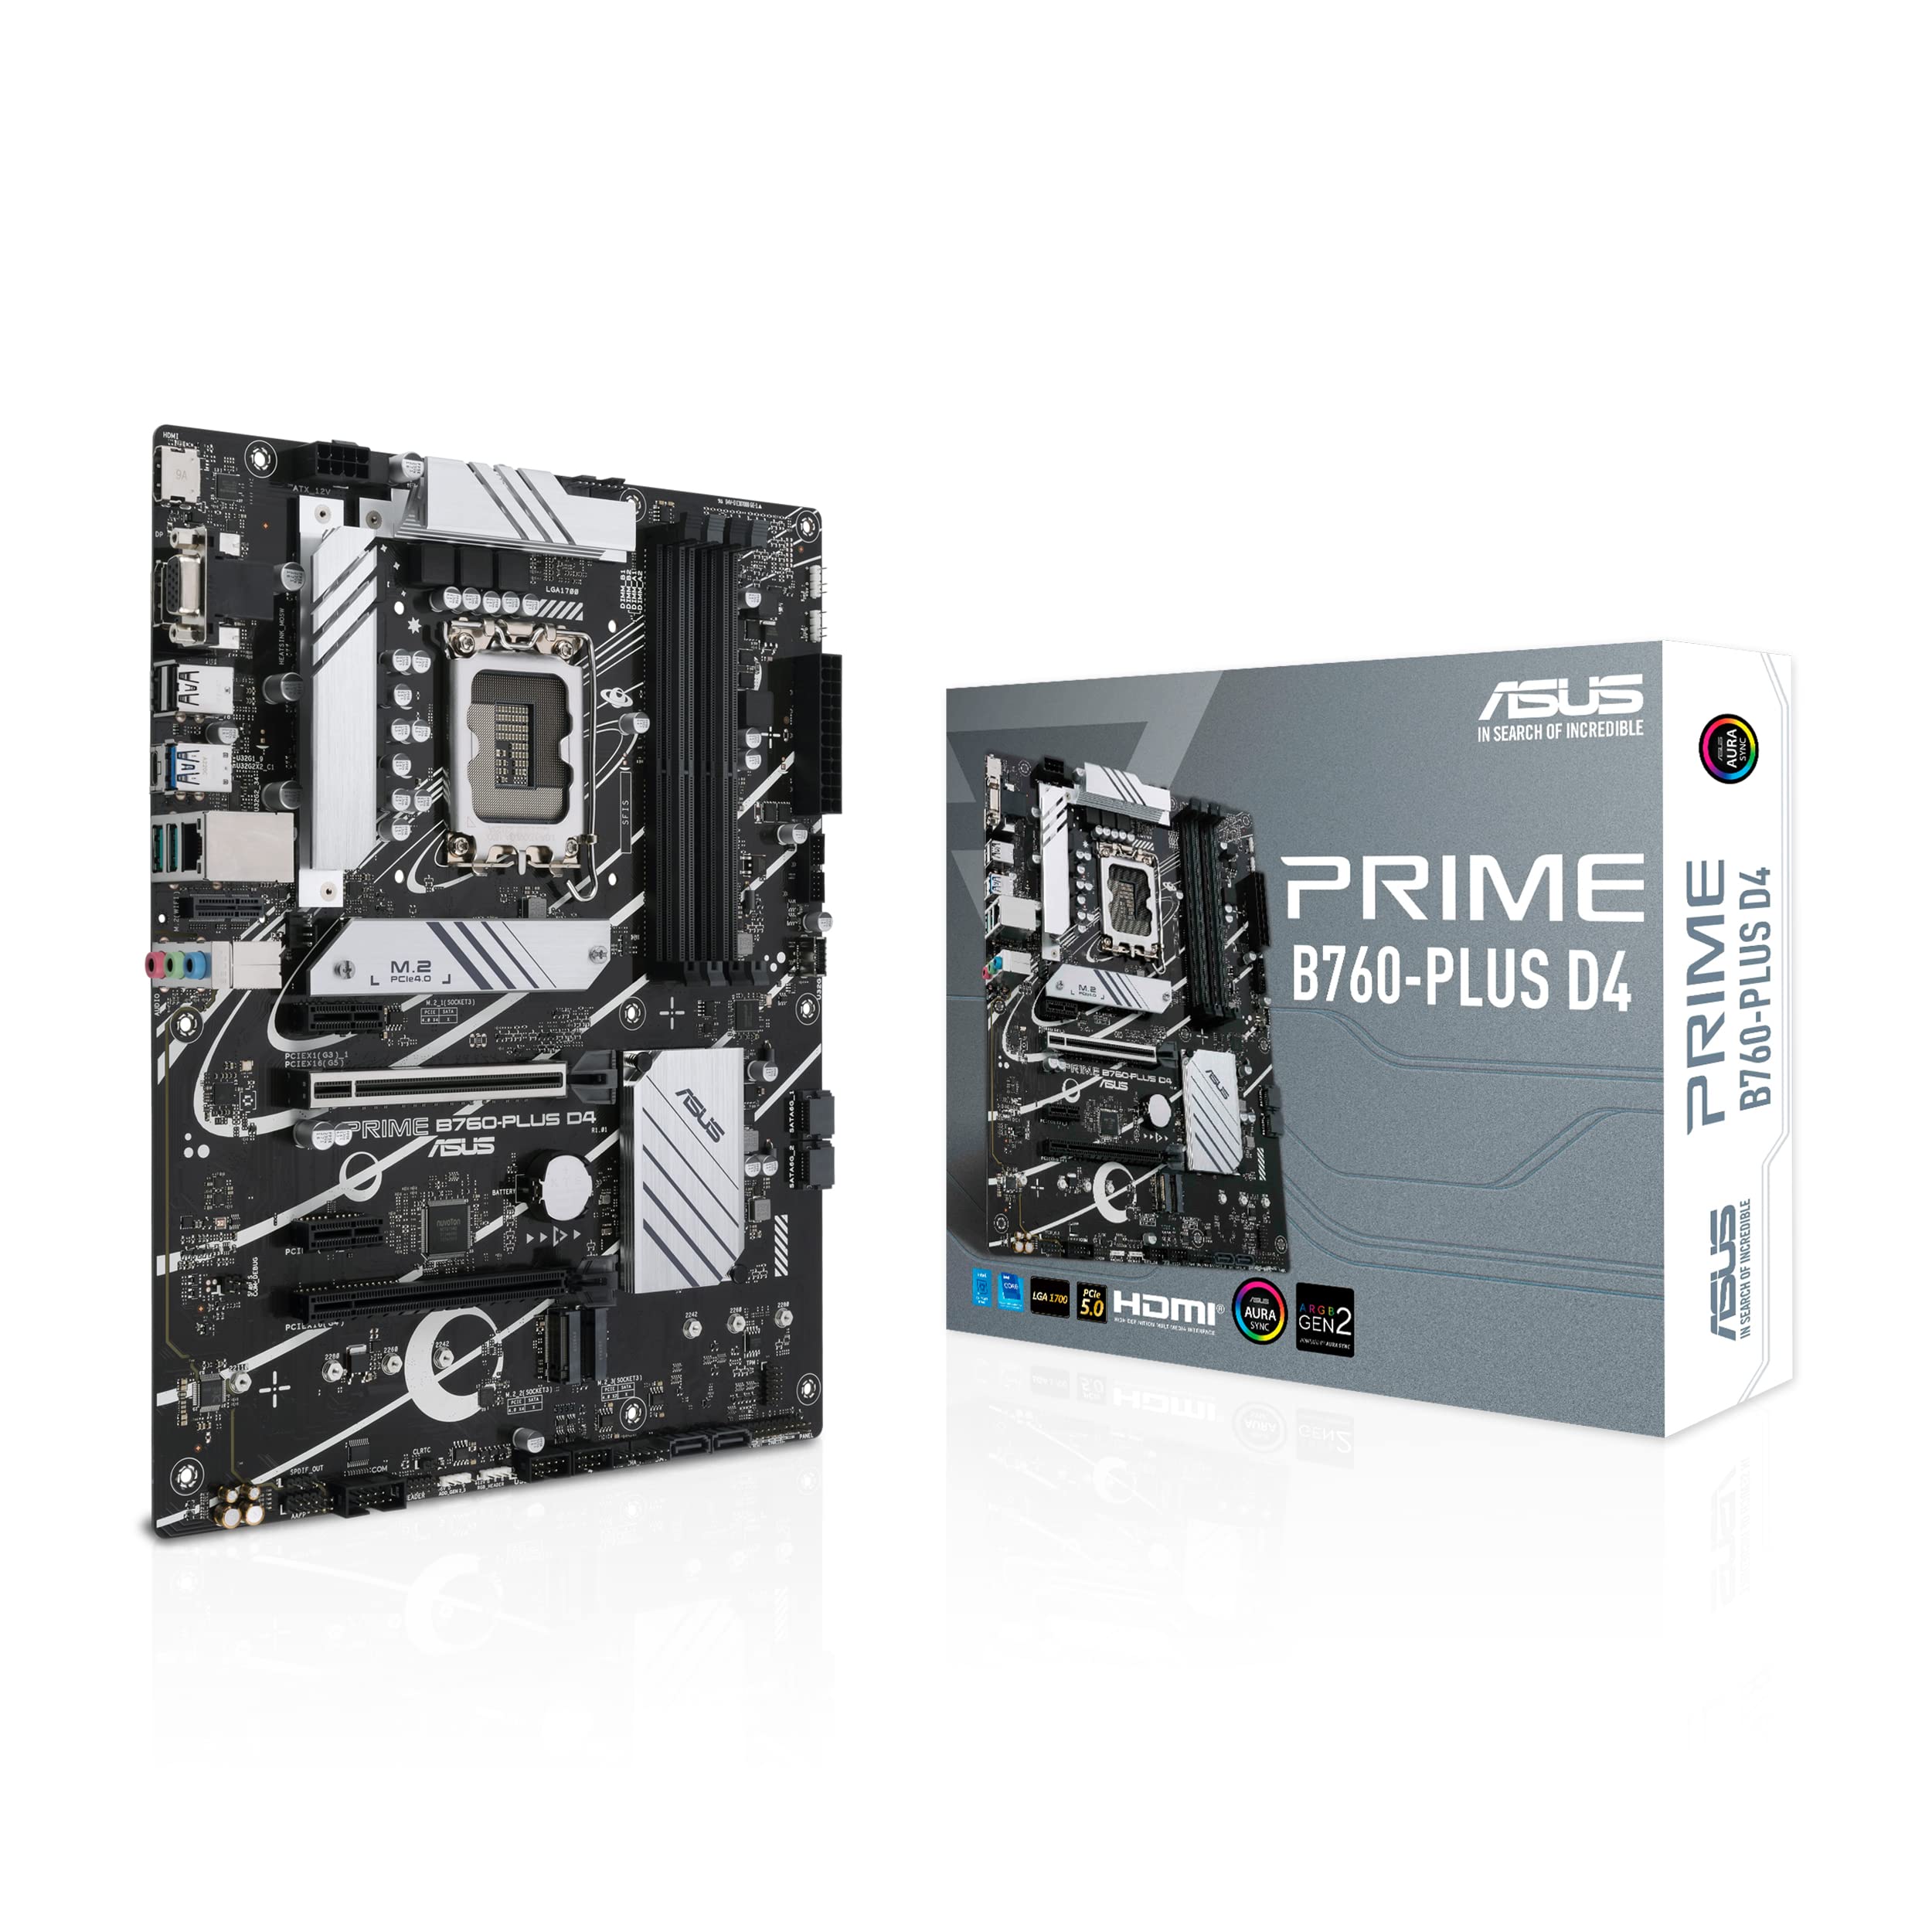 €122Preise werden gesucht…
 ramG.Skill Trident Z Royal Silver DDR4-3200 CL14 128GB (4x32GB)128 GB DDR4 · 3200 MT/sAlternativen & Tausch≈ €852Preise werden gesucht…
 €35Preise werden gesucht…
 €8Preise werden gesucht…
 €152Preise werden gesucht…
 €474Preise werden gesucht…
 €6,443Preise werden gesucht…
Zukunftssicherheits-Score
Starke Zukunftssicherheit77/100
Strong future-proofing (77/100) — this build should stay relevant for years without major surgery.
DIY build — the CPU, motherboard and PSU can each be upgraded independently without replacing the whole system.
Expansion headroom: 2 PCIe slot(s), 6 M.2, 4 SATA, 2 drive bay(s), 0 RAM slot(s) free.
Storage is 100% utilized with 2 free drive bay(s) and 4 free SATA port(s).
0 RAM slot(s) free; memory is 75% utilized.
Networking is 2500 Mbps, and a free PCIe slot can add a faster NIC later.
ATX form factor with standard, socketed components — most parts are easy to replace.
A 32GB GPU is present — AI and transcoding workloads are covered.
Homelab-Risiko-Score
Geringes Risiko21/100
Low risk (21/100) — sensible redundancy and headroom; no single point of failure is exposed.
Finaler Build-Audit
Audit passed (0 critical, 0 warning) — mostly optional and future considerations remain.
Was zum Limit wird
RAM is maxed out is the most likely thing to date this build within 1-2y.
Was dich zuerst begrenzt
Storage is the closest to its limit (100% of capacity in use) — it will likely force the next upgrade.
- Upgrade storage to Seagate Exos X22 22TB HDD 3.5" SATA
- Add Microconnect MC-PCIEX4-X520-DA1 network card Internal Fiber 10000 Mbit/s
- Add Seagate Constellation ES.3 4TB 3.5" HDD 7200RPM SAS 6.0 Gb/s
Mission
- Budget
- —
- Energiepriorität
- 3/10
- Lautstärkepriorität
- 2/10
- Erweiterungspriorität
- 5/10
Empfohlene Architektur
diy · tower build on LGA 1700 + Intel B760- Rechenleistung
- Intel Core i7 14700
- Speicher
- G.Skill Trident Z Royal Silver DDR4-3200 CL14 128GB (4x32GB)
- Speicher
- TEAMGROUP MP44 4TB M.2-2280 SSD PCIe 4.0 x4 NVMe
- Netzwerk
- 2.5G onboard
- Kühlung
- ARCTIC Alpine 17 CO Air 77mm Black
- Netzteil
- Thermaltake Toughpower GT 1000W Black
- Erweiterung
- 2× PCIe, 6× M.2, 4× SATA, 2 bay